Webpages tagged with «superpixels»
Published Aug. 19, 2024 12:58 PM
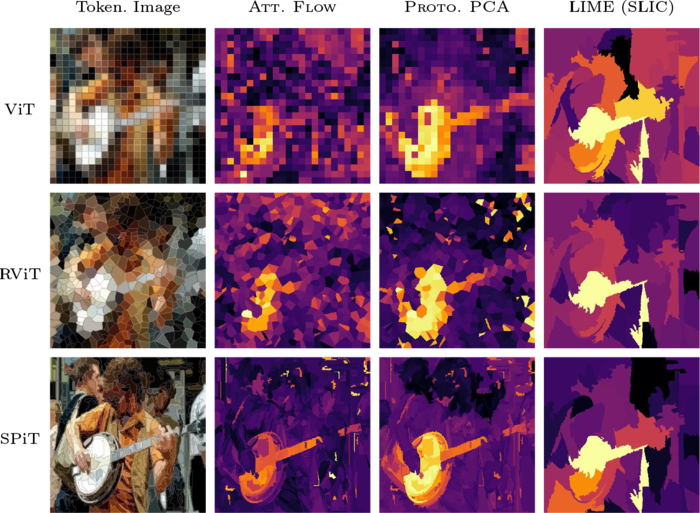
The Vision Transformer (ViT) signifies a new direction in modelling spatial data, representing a shift in focus from local spatial interactions to global contextual relationships. Traditionally, ViTs partition images into square patches to extract tokenized features. But is this necessarily an optimal way of partitioning images for transformers?