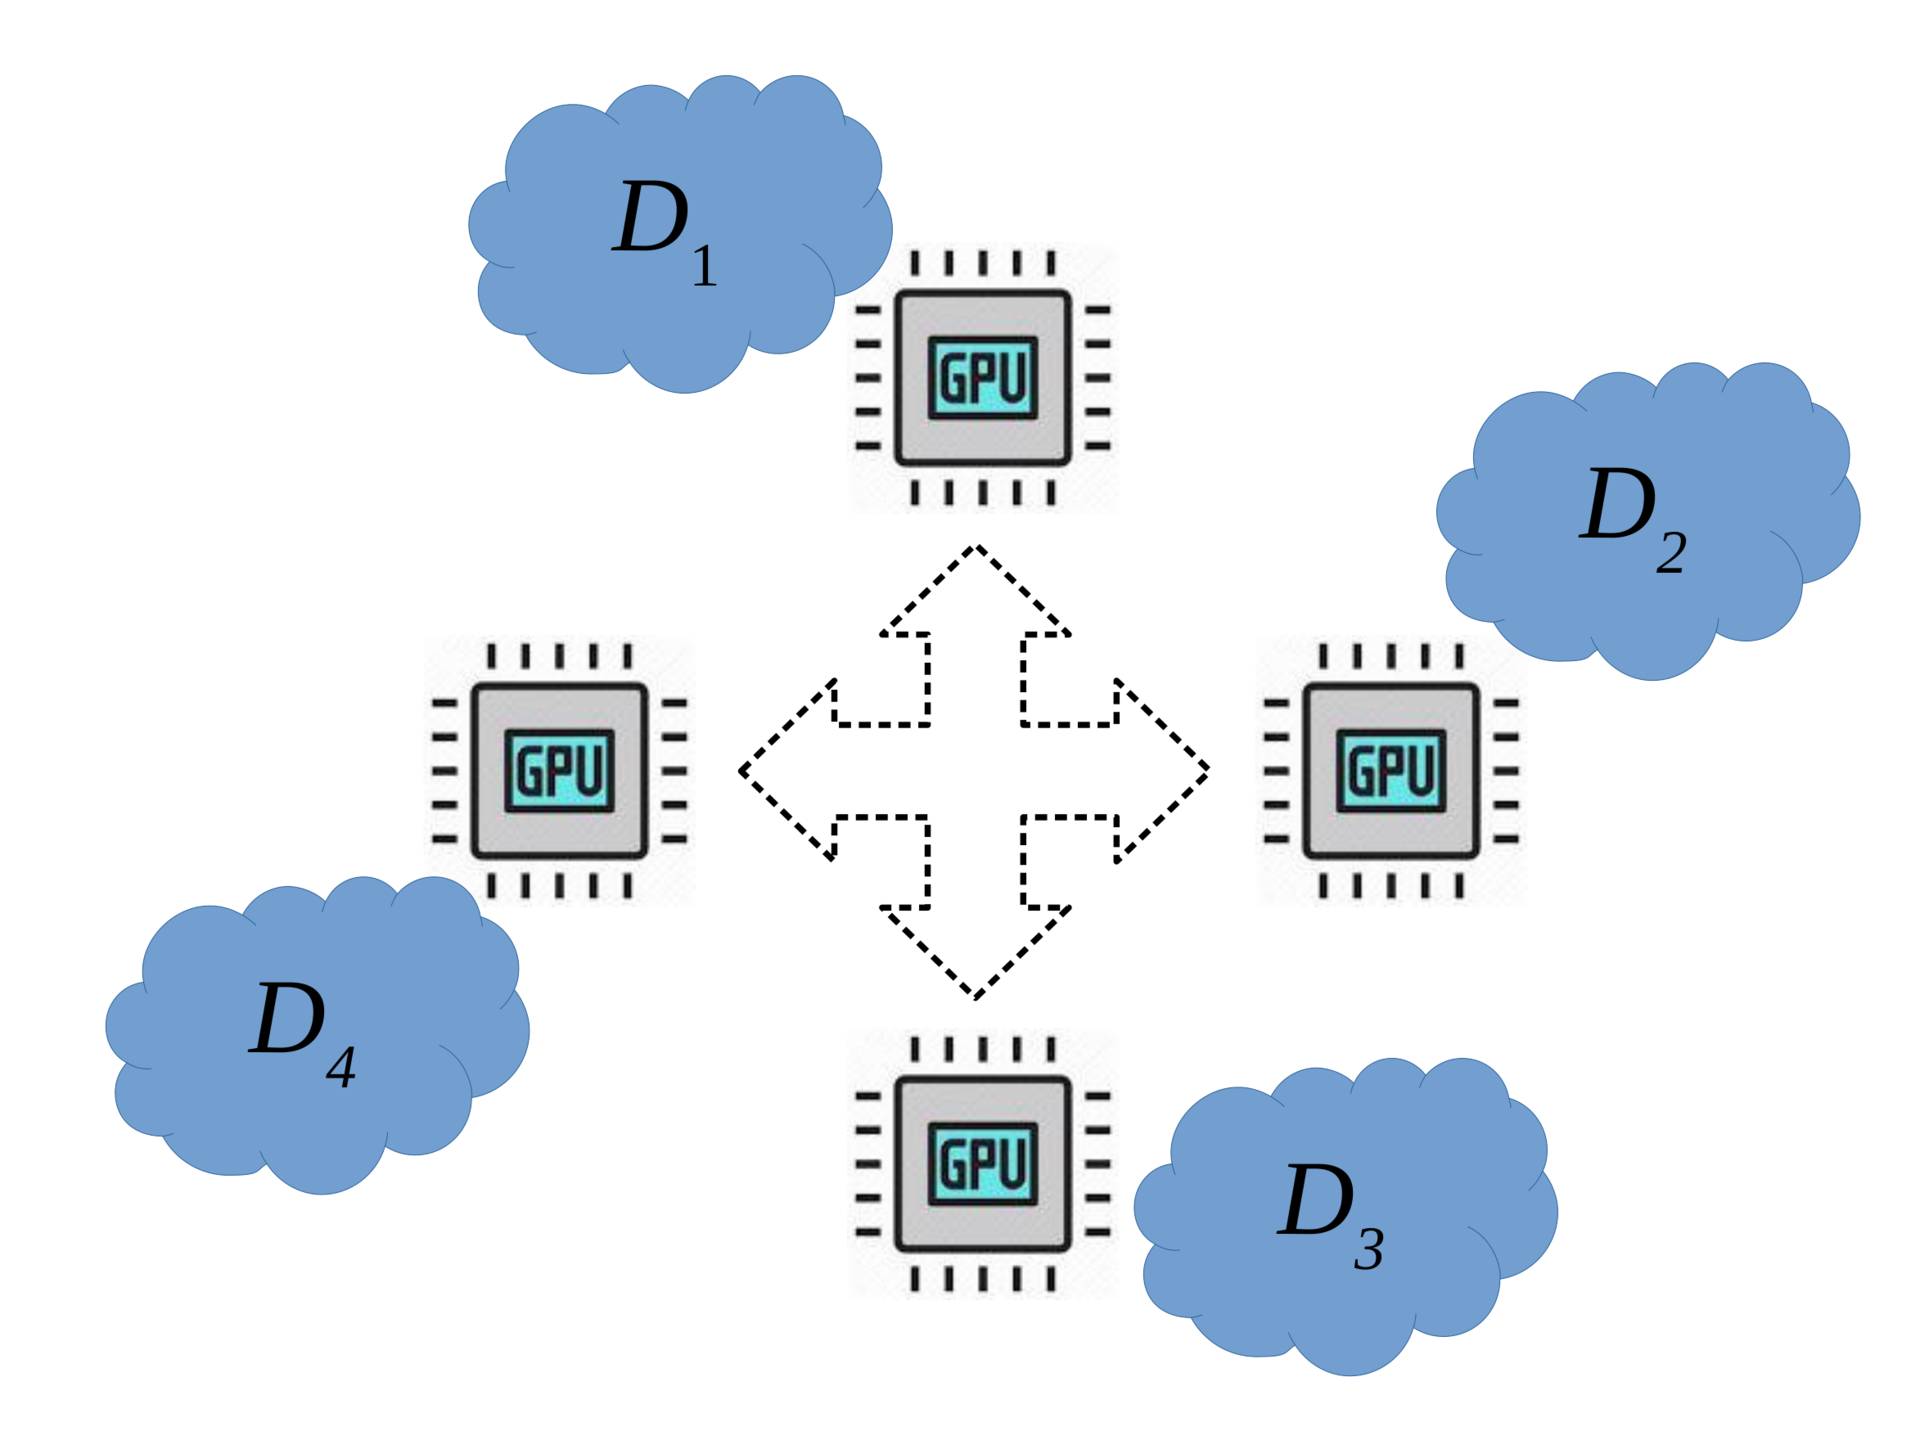
GPT-3 has been trained on 10,000 V100 GPUs in a Microsoft cloud data center with unprecedented communication costs and Carbon footprint. The total emissions of training Llama 2 family of models and GPT-3 are estimated to be 539 and 552 tons of CO2 equivalent, respectively, which is not sustainable. Quantization, sparisification, and pruning of the underlying neural networks and data movement minimization are proposed to make ML more efficient as data movements between global and shared memory dominates the energy consumption of hardware platforms and the total energy consumption is a monotonically increasing function of the model size.
We have significantly accelerated ML in multi-node systems, i.e., handled scalability issues by developing highly communication-efficient and large-scale training in supervised learning, and training deep generative adversarial networks without sacrificing accuracy [1–3].
In this work, you will continue my current work with our undergrad summer intern from math department (Oskar). He spent a summer with me on a problem and did a super great job. We now plan to submit his work to top ML conference ICLR.
This project is available for a master student with a background in machine learning. If interested, please contact Ali Ramezani-Kebrya for details.
[1] Fartash Faghri, Iman Tabrizian, Ilia Markov, Dan Alistarh, Daniel M. Roy, and Ali Ramezani-Kebrya. Adaptive gradient quantization for data-parallel SGD. In Advances in Neural Information Processing Systems (NeurIPS), 2020.
[2] Ali Ramezani-Kebrya, Fartash Faghri, Ilya Markov, Vitalii Aksenov, Dan Alistarh, and Daniel M. Roy. NUQSGD: Provably communication-efficient data-parallel SGD via nonuniform quantization. Journal of Machine Learning Research (JMLR), 22(114):1–43, 2021.
[3] Ali Ramezani-Kebrya, Kimon Antonakopoulos, Igor Krawczuk, Justin Deschenaux, and Volkan Cevher. Distributed extra-gradient with optimal complexity and communication guarantees. In International Conference on Learning Representations (ICLR), 2023.