Description of the topic
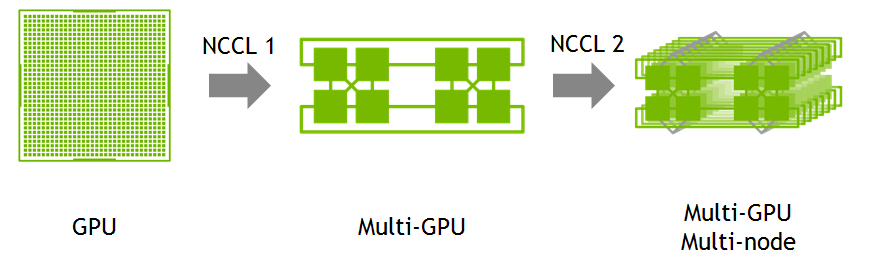
NCCL is used to communicate between multiple GPUs and multiple machines with GPUs when doing distributed Deep Learning Training. When using multiple computers, NCCL uses TCP/IP or InfiniBand to communicate. NCCL supports an arbitrary number of GPUs installed in a single node or across multiple nodes and can be used in either single- or multi-process (e.g., MPI) applications.
The tasks for the master project will be to:
- Benchmark and analyze the performance and energy efficiency of the existing NCCL implementation with TCP/IP
- Use TCP/IP over PCIe to get a baseline performance.
- Write an optimized PCIe transport for NCCL
- Contribute code back to the open-source NCCL project.
Goal
Implement PCIe transport in the NVIDIA Collective Communications Library (NCCL) and use Deep Learning Training to benchmark the implementation.
Learning outcome
In-depth knowledge of how to distribute workloads over multiple machines connected in a PCIe network. The student will also get detailed insight into working with and modifying, and contributing code to an existing open-source library.
Qualifications
Good understanding of C or C++ programming. IN3000 or equivalent is recommended.