Approach
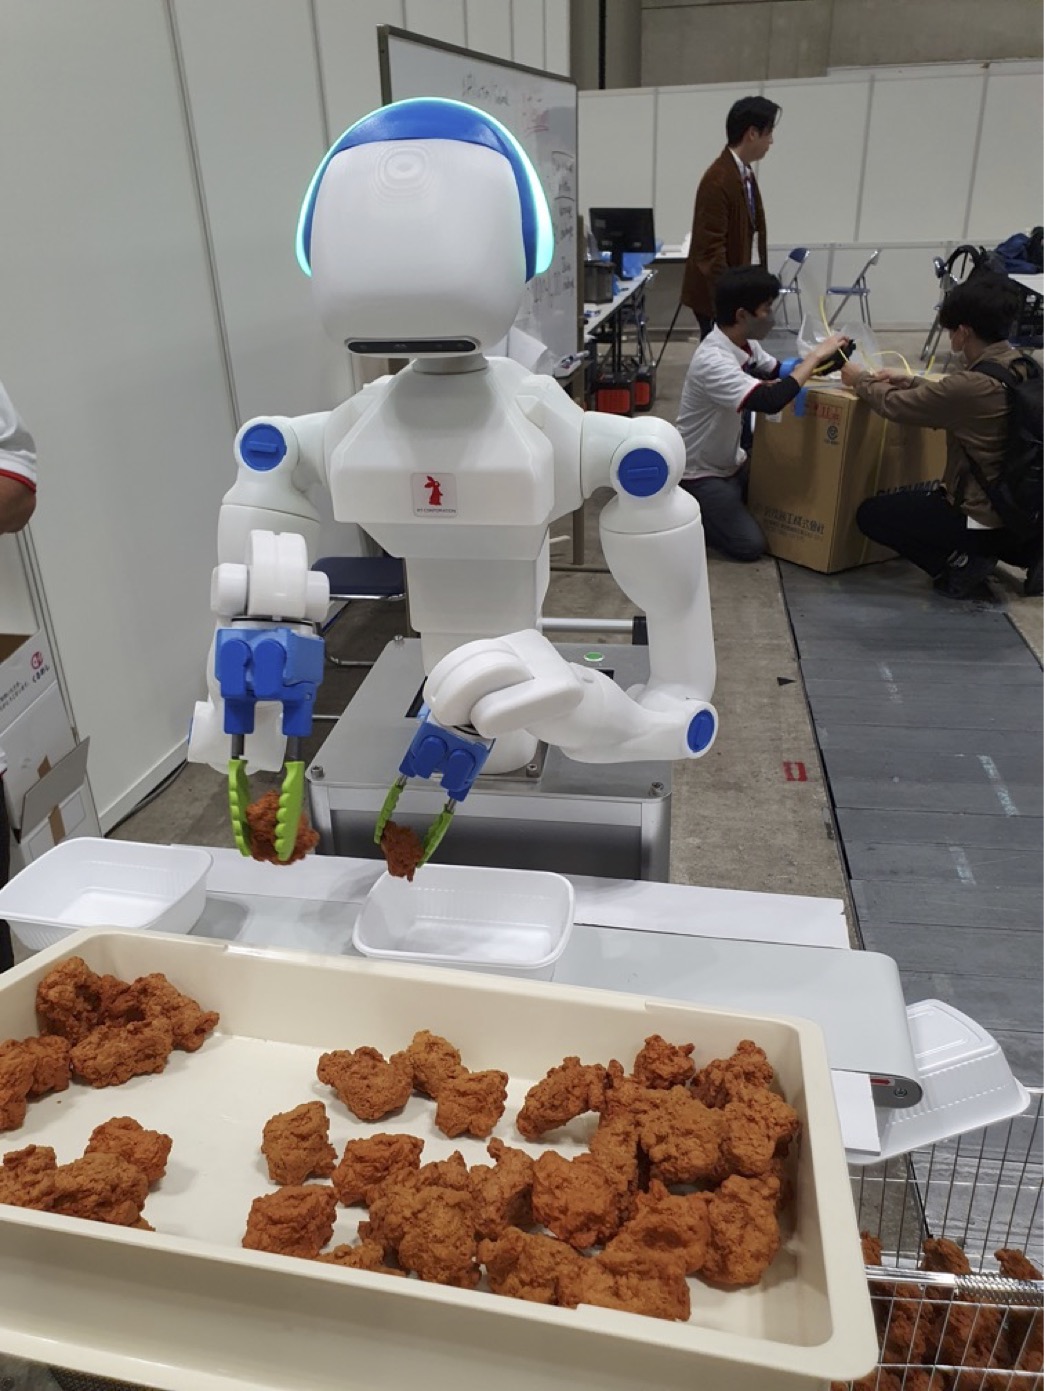
In this project we would like to demonstrate a robots’ ability to find, put together and bring food based on different food ingrediencies and user food preferences. The project can be undertaken in simulation only or a mix of simulation and real testing with TIAGo or UR5 arm.
Project Plan
The project could contain the following parts:
- Review literature on VLMs applied in robotics and with a special focus on food preparation applications
- ICRA2024 Workshop on cooking robotics: https://sites.google.com/view/icra2024cookingrobotics/
- Implement a prototype system for receiving text input from a user about requested food
- Consider the food ingrediencies available and select what seems to be a best possible match to the request
- Consider undertaking user testing of the prototype
- Consider adding a health consideration part taking healthy choices into consideration
Existing models:
Consider using the gpt-4o model via API provided by OpenAI, see https://platform.openai.com/overview
Segment Anything Model (SAM) (Kirillow et al, 2023) can be applied to identify and segment any object in an image. A Contrastive Language-Image Pre-training (CLIP) (Radfor et al, 2021) model can be applied to understand and generate representations for a wide range of visual concepts described in text by a user. There are work a tidy up tasks that can be relevant (Wu et al, 2023).
References
- ICRA2024 Workshop on cooking robotics: https://sites.google.com/view/icra2024cookingrobotics/
- J. Wu, R. Antonova, A. Kan, M. Lepert, A. Zeng, S. Song, J. Bohg, S. Rusinkiewicz, and T. Funkhouser, “Tidybot: Personalized robot assistance with large language models,” arXiv preprint arXiv:2305.05658, 2023.
- Brohan, A., et al. (2023). RT-2: Vision-Language-Action Models Transfer Web Knowledge to Robotic Control. [https://arxiv.org/abs/2307.15818]
- A. Kirillov, E. Mintun, N. Ravi, H. Mao, C. Rolland, L. Gustafson, T. Xiao, S. Whitehead, A. C. Berg, W.-Y. Lo et al., “Segment anything,” arXiv preprint arXiv:2304.02643, 2023.
- A. Radford, J. W. Kim, C. Hallacy, A. Ramesh, G. Goh, S. Agarwal, G. Sastry, A. Askell, P. Mishkin, J. Clark et al., “Learning transferable visual models from natural language supervision,” in International conference on machine learning. PMLR, 2021, pp. 8748–8763.