Arrangementer - Side 3
This talk will focus on recent work about the sequential detection of anomalies within partially observed functional data, motivated by a problem encountered by an industrial collaborator. Classical sequential changepoint detection approaches look for changes in the parameters, or structure, of a data sequence and are not equipped to handle the complex non-stationarity and dependency structure of functional data. Conversely, existing functional data approaches require the full observation of the curve before anomaly detection can take place. We propose a new method, FAST, that performs sequential detection of anomalies in partially observed functional data. This talk will introduce the approach, and some associated theoretical results, and highlight its application on telecommunications data.
This is joint work with Idris Eckley and Lawrence Bardwell.

A flexible predictive density combination is introduced for large financial data sets which allows for model set incompleteness. Dimension reduction procedures that include learning allocate the large sets of predictive densities and combination weights to relatively small subsets. Given the representation of the probability model in extended nonlinear state-space form, efficient simulation-based Bayesian inference is proposed using parallel dynamic clustering as well as nonlinear filtering, implemented on graphics processing units. The approach is applied to combine predictive densities based on a large number of individual US stock returns of daily observations over a period that includes the Covid-19 crisis period. Evidence on dynamic cluster composition, weight patterns and model set incompleteness gives valuable signals for improved modelling. This enables higher predictive accuracy and better assessment of uncertainty and risk for investment fund management.
Online changepoint detection algorithms based on likelihood-ratio tests have excellent statistical properties. However, a simple exact online implementation is computationally infeasible as, at time T, it involves considering O(T) possible locations for the change. To improve on this, we use functional pruning ideas to reduce the set of changepoint locations that need to be stored at time T to approximately log T. Furthermore, we show how we need only maximise the likelihood-ratio test statistic over a small subset of these possible locations. Empirical results show that the resulting exact online algorithm, which can detect changes under a wide range of models, has a constant-per-iteration cost on average. We consider applications of this algorithm in the context of detecting increases in radiation count that represent astronomical or nuclear events of interest.
This talk will introduce a recent suite of research focussed on the statistical detection of anomalous structure in online data settings. The challenge of efficiently identifying anomalies in data sequences is an important statistical problem that now arises in many applications. Whilst there has been substantial work aimed at making statistical analyses robust to outliers, or point anomalies, there has been much less work on detecting anomalous segments, or collective anomalies, particularly in those settings where point anomalies might also occur. This is the challenge we seek to address, demonstrating theoretical results in both the offline and online settings as well as introducing some applied case studies.
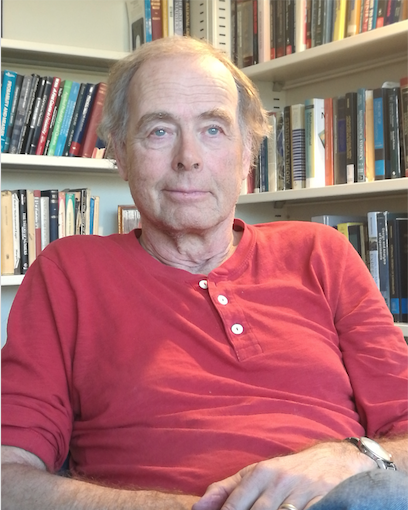
Douglas Wiens (Department of Mathematics and Statistical Sciences, University of Alberta, CAN) will give a talk on Wednesday April 19th at 14:15 in the Erling Sverdrups plass, Niels Henrik Abels hus, 8th floor.
Variable selection methods based on L0 penalties have excellent theoretical properties to select sparse models in a high-dimensional setting. There exist modifications of BIC which either control the family wise error rate (mBIC) or the false discovery rate (mBIC2) in terms of which regressors are selected to enter a model. However, the minimization of L0 penalties comprises a mixed integer problem which is known to be NP hard and therefore becomes computationally challenging with increasing numbers of regressor variables. This is one reason why alternatives like the LASSO have become so popular, which involve convex optimization problems which are easier to solve. The last few years have seen some real progress in developing new algorithms to minimize L0 penalties. We will compare the performance of these algorithms in terms of minimizing L0 based selection criteria.
Simulation studies covering a wide range of scenarios which are inspired by genetic association studies are used to compare the values of selection criteria obtained with different algorithms. Additionally some statistical characteristics of the selected models and the runtime of algorithms are compared.
Estimates of environmental extremes are needed for a multitude of applications. For example, buildings, roads, bridges and dams must be designed to withstand extreme precipitation and flooding events of a certain size. Obtaining such estimates requires a combination of statistical theory and environmental process understanding to overcome data deficiencies: data on extremes are by definition sparse and regulations often require estimates for events that have yet to be observed. We will present approaches to obtain consistent estimates across spatial locations and accumulation periods, and discuss a few open questions on this topic.
On the occasion of Jørund Gåsemyr retiring earlier this year, we invite you to a half-day seminar celebrating his contributions to statistics over many years.
We are delighted to finally again be able to invite you to the Klækken seminar, October 11 – October 12, 2022. Klækken seminar is open for young researchers in temporary positions within statistics/biostatistics/bioinformatics at OCBE (UiO and OUS), Institute of Mathematics (UiO), BiAs (NMBU) and RealTek (NMBU). It is meant as an arena to get to know each other across the institutes and to practice your presentations skills in front of a friendly and harmless audience.
We invite you (once again) to a two-day seminar celebrating Professor Ørnulf Borgans many and substantial contributions to statistics in general and life event history analysis in particular.


We introduce SMARTboost (boosting of symmetric smooth additive regression trees), a machine learning model capable of fitting complex functions in high dimensions, yet designed for good performance in small n and low signal-to-noise environments. SMARTboost inherits many of the qualities that have made boosted trees the most widely used machine learning tool for tabular data; it automatically adjusts model complexity, handles continuous and discrete features, can capture nonlinear functions in high dimensions without overfitting, performs variable selection, and can handle highly non-Gaussian features. The combination of smooth symmetric trees and of carefully designed Bayesian priors gives SMARTboost an edge (in comparison with a state-of-the-art tool like XGBoost) in most settings with continuous and mixed discrete-continuous features. Unlike other tree-based methods, it can also compute marginal effects.
Maintenance plays a crucial role in ships and especially in the vital electric propulsion system. Intelligent predictive maintenance idealistically aims at preventing system failures and minimizing needless repairs, i.e., predicting failure likelihood and time to failure while providing the crew explainable predictions and recommending the best action for timely intervention. This presentation will cover a relevant work in collaboration with Sensor Systems in BigInsight, particularly a paper published under https://doi.org/10.1109/TII.2022.3144177. The failure prediction approach is driven by event logs, which include warnings, alarms, and operational information that describe all the happenings onboard the ship. The failure prediction objective is turned into classification and regression tasks; however, the training data pose three challenges. The events are irregular textual messages. The training data samples are not labelled. The datasets are extremely imbalanced, due to sparse failure events and multiple failure modes. The problem is casted into a weakly supervised machine learning framework. In a multiple instance learning process, the ungiven data labels are learned recursively while fitting the model parameters using deterministic annealing. The overall approach was tested on real ship data, and it successively forecasted few propulsion failures with explainable causes.
Deep learning (DL) has had unprecedented success and is now entering scientific computing with full force. However, current DL methods typically suffer from instability, even when universal approximation properties guarantee the existence of stable neural networks (NNs). In this talk we will show that there are basic well-conditioned problems in scientific computing where NNs with great approximation qualities are proven to exist, however, there does not exist any algorithm, even randomised, that can train (or compute) such a NN to even 1-digit of accuracy with a probability greater than 1/2. These results provide basic foundations for Smale’s 18th problem ("What are the limits of AI?") and imply a potentially vast classification theory describing conditions under which (stable) NNs with a given accuracy can be computed by an algorithm. We begin this theory by initiating a unified theory for compressed sensing and DL, leading to sufficient conditions for the existence of algorithms that compute stable NNs in inverse problems. We introduce Fast Iterative REstarted NETworks (FIRENETs), which we prove and numerically check (via suitable stability tests) are stable. The reference for this talk is: https://arxiv.org/abs/2101.08286 (to appear in Proc. Natl. Acad. Sci. USA).
Super-resolution is a hot topic in current day Machine Learning. The origin of the methodology dates back to applications in seismic imaging. I discuss the evolution from the early days and highlight some papers which have given new theoretical insights along the way. I illustrate the bridge between traditional convex optimization and current day convolutional neural nets. Along the way I show some examples where we have used this for current day applications in seismic imaging.

For many real-life phenomena one may assume that the units of observation, typically patients, transition through a set of discrete states on their way towards an absorbing state. The states often constitute various stages of a disease, from perfect health through various stages of dementia for example. Multi-state models are a class of statistical models which allow us to study the time spent in different states, the probability of transitioning between states, and the relationship between these quantities and covariates of interest. In many applications the transition times between states are not observed exactly; instead, the current state of the patients is queried at arbitrary times. The transition times are therefore interval censored, and this makes inference and modelling challenging. Most current approaches are based on the Markov assumption, for example the simplest parametric model available - the time-homogeneous Markov model. Here, we propose a new, general framework for parametric inference with interval censored multi-state data. Our models allow non-Markovian behaviour. I will present the framework and an algorithm for the automatic construction of the likelihood function, along with real-data examples. This talk is based on joint work with Marthe Aastveit and Nils Lid Hjort.
Cards are drawn, one at a time, with replacement, from a deck of n cards. I study the total time W_n needed until we have seen all n cards, via different perspectives, along with a Gumbel limiting distribution. Various non-trivial identities, involving different perspectives for moments and Laplace transformations, are found as corollaries. These findings are also used to estimate the number of different cards,if uknown. If I needed to sample 133 words from a document, before I had 50 different words, what is the vocabulary size for the document? How many words did Shakespeare know (including those he never used in his writing)?
An Abels Tårn podcast about some of these themes, which attracted a fair amount of inspired comments and guesses from the public (specifically, finding the mean of W_n above, for the case of n = 52 cards), can be found on the Abels Tårn website, July 2021, as a conversation with Torkild Jemterud, Jo Røislien, and myself.