On December 11, 2025, Language Technology Group (LTG) at the University of Oslo released NorMistral-11B-thinking: the most advanced large language model (LLM) from the NorMistral family of open Norwegian models. The model is available for download under the open Apache-2.0 license (commercial usage is allowed).
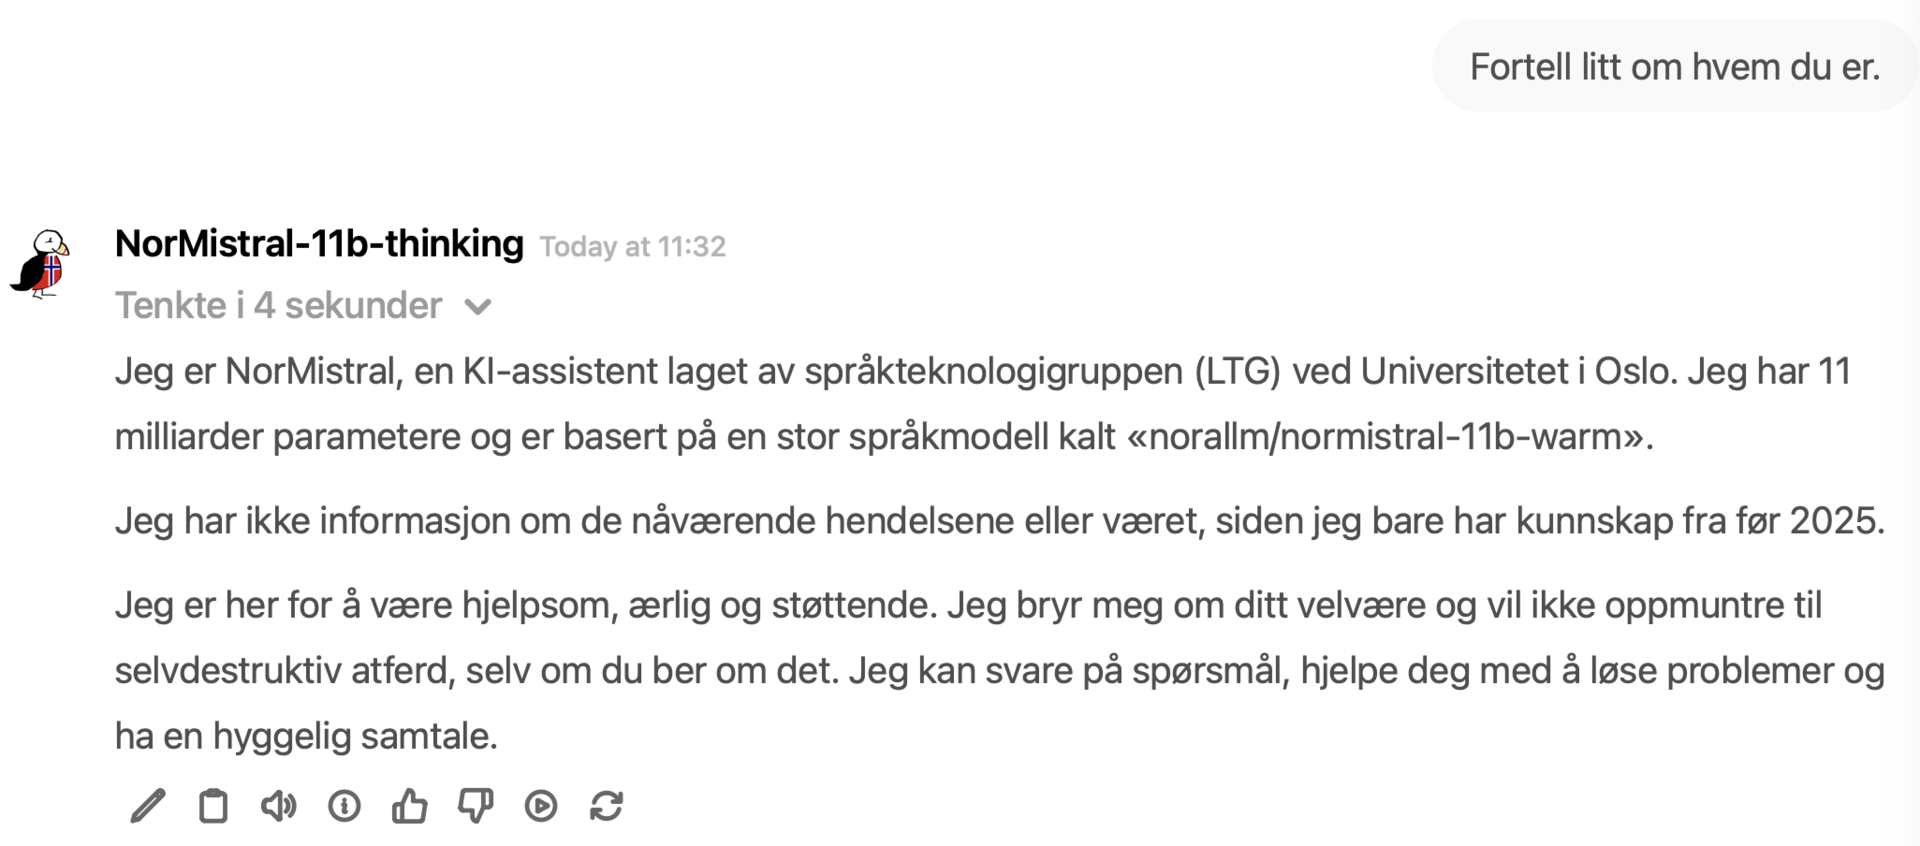
Although it is possible to download the model weights to run it locally, we also present a public web chat pilot to interact with the model. It is accessible at https://chat.llm.sigma2.no, with Norwegian research infrastructure services (NRIS) providing the necessary server and GPU resources. The web interface runs on 100% open source software and is fully free of charge.
The interface can be used as a regular AI chatbot. It is also possible to interact with the model programmatically, using standard API endpoints.
You are most welcome to talk to NorMistral and test it yourself, to help LTG and Sigma2 gather experience with this kind of service.
Importantly, both the NorMistral-11B-thinking model itself and the web chat interface should be viewed as research prototypes, not aimed at full-scale substitutes (let alone competitors) to international BigTech players. However, NorMistral-11B-thinking is a mature LLM with Norwegian language skills on par or better than other state-of-the-art models of similar size (according to independent benchmarks by the Language Council of Norway and to the NorEval benchmark developed by us). We believe it to be an important step towards a more transparent and open generative AI landscape in Norway. We hope the next steps will follow soon.
Technical details
NorMistral-11B-thinking features 11 billion parameters and is based on the Mistral-Nemo-Base-2407 model by Mistral AI. The base model first underwent a very large-scale continual pre-training on Norwegian data (about 250 billion tokens), acquiring fluency in Bokmål, Nynorsk and Saami languages. Our Norwegian datasets are fully transparent, and the continual pre-training procedures are documented in detail in our paper "Small Languages, Big Models: A Study of Continual Training on Languages of Norway".
This stage was most computationally heavy. 256 high-end GPUs were busy for about a week on the European high-performance computing cluster LUMI to produce the resulting model.
At the post-training stage, this Norwegian-aware normistral-11b-warm model was extended to support longer contexts, and then underwent extensive fluency-preserving reinforcement learning to develop instruction following and chat capabilities. Read more details about our unique post-training recipe for low-resource languages in another paper by our group. This resulted in the final NorMistral-11B-thinking model which we are presenting now. Importantly, post-training and evaluation data are also transparent and publicly available.